Language AI & NLP
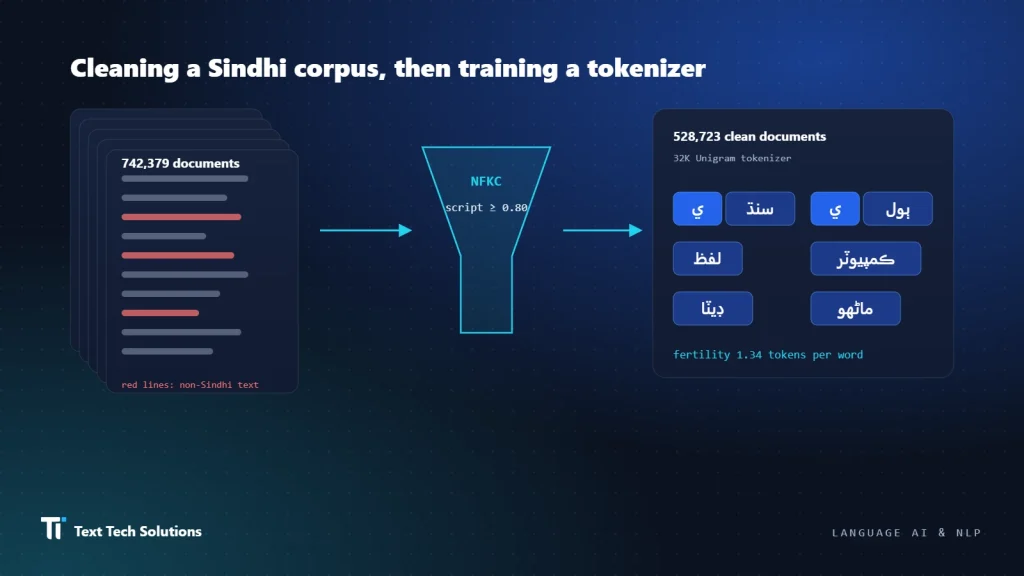
What we learned cleaning a Sindhi text corpus before training a tokenizer
Low-resource language models live or die by data quality. Lessons from auditing a large Sindhi corpus, filtering it, and training a 32K Unigram tokenizer on the…
6 min read